

Nutrient Data Extraction API
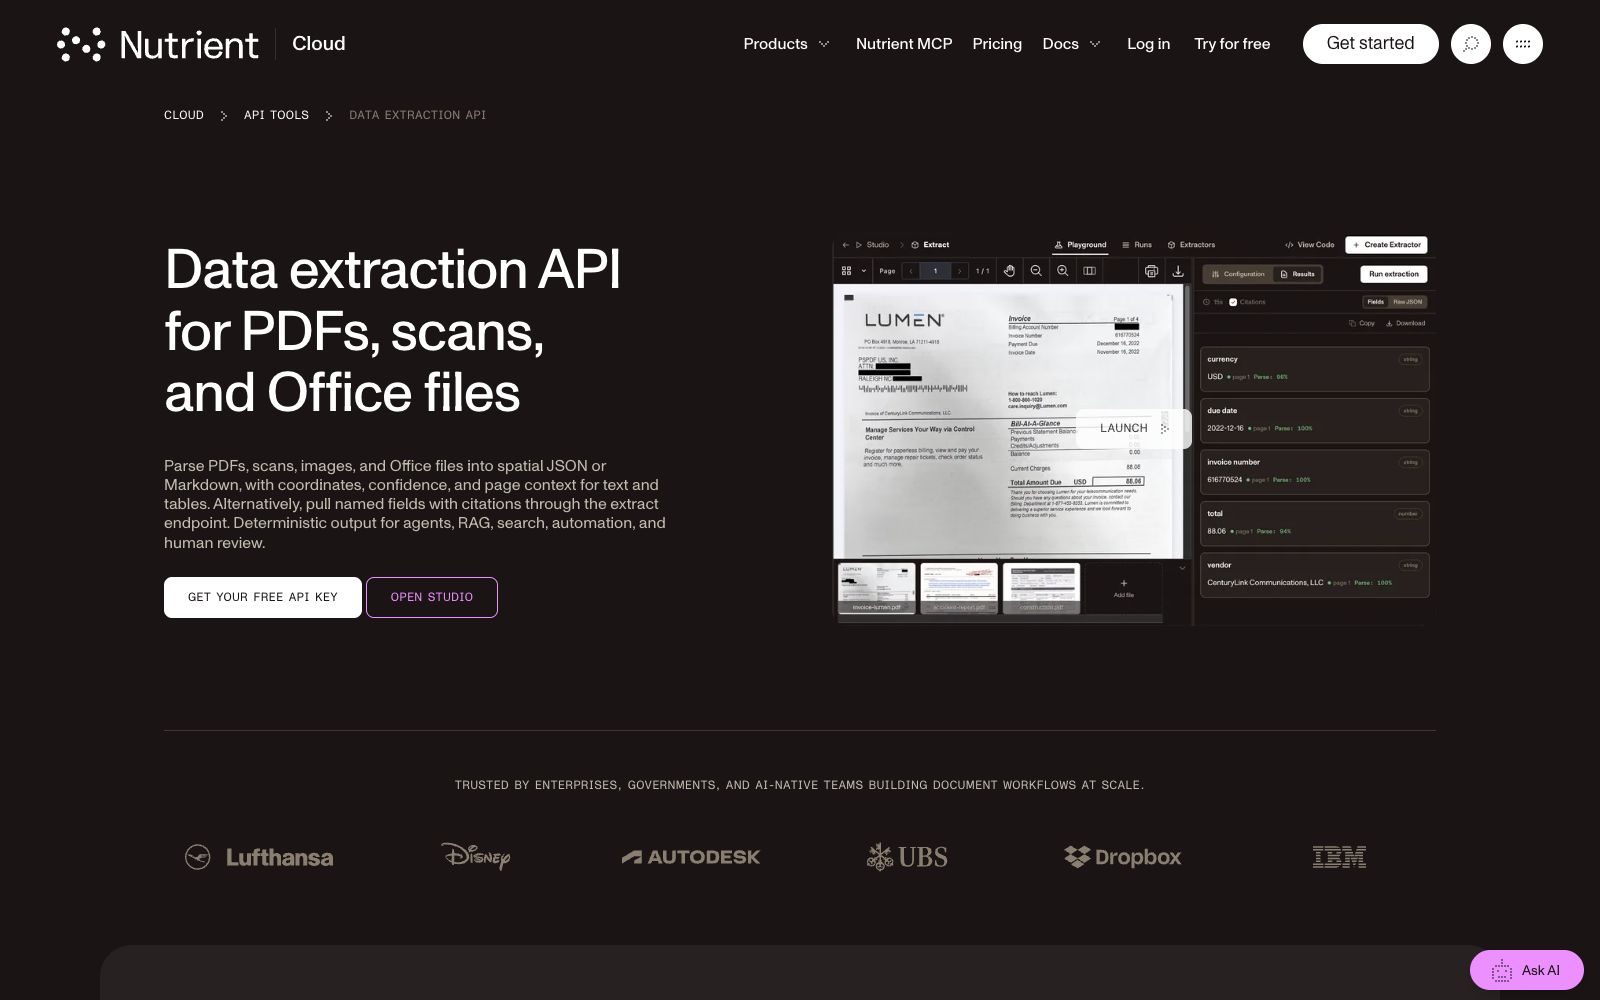
Nutrient's cloud document extraction interface parses PDF, scanned documents, images and Office files into spatial JSON or Markdown with coordinates, confidence and page number context. It can also extract by field name with reference sources. The official website states that the free quota is 5,000 credits per month.
Updated: 2026-10-26
What is Nutrient Data Extraction API?
The Nutrient Data Extraction API is a cloud-based document parsing interface provided by Nutrient. Its official website positioning is "Data extraction API for PDFs, scans, and Office files" — it parses complex files into structured JSON or Markdown. Different from interfaces that only extract pure text, its output includes element type, bounding box, confidence level, reading order and page number context, and offers four processing modes: text, structure, understand, and agentic, allowing you to choose based on cost and accuracy.
Who is it for?
- Teams engaged in RAG, search, and knowledge base development who need to batch convert scanned documents and Office files into Markdown.
- For financial and accounts payable processes handling invoices, receipts, and statements, the official website lists AP collection, three-way matching, and ERP synchronization.
- Regulated businesses handling mortgage loans, KYC documents, insurance claims, and legal contracts require coordinate and confidence traceability for review.
- Medical information teams working on medical record digitization and claim review.
- Developers equipping coding agents with document skills; the official website offers two integration methods: Data Extraction skill and MCP.
Key features
6Structured Parsing
Parses PDFs, images, Office documents and scanned files into spatial JSON or Markdown. The official website states that it can recognize tables, forms, formulas, charts, handwritten text, headings and reading order.
Named Field Extraction
Returns values based on the field names you declare, with each value accompanied by bounding boxes and matching tags; the official website states that `understand` is the recommended extraction mode.
Four-gear Processing Mode
text is low-cost Markdown for native digital PDFs; structure outputs spatial JSON with OCR, tables, boundaries and confidence levels; understand is for forms, complex layouts, printed handwritten text and OCR correction; agentic uses visual reasoning to handle cursive handwritten text and degraded scanned documents.
Automatic Routing
The official website recommends starting with `auto` to let the system route requests to specific modes page by page; explicitly specify the mode only when you need to control depth and costs.
Reviewable results
Elements come with coordinates, confidence levels and page number context; the official website states this can be used for verification, highlighting and manual review.
Multiple connection methods
curl, Python, JavaScript, Java, C#, PHP and other languages can call the same set of endpoints; you can also use Nutrient MCP to let Claude Code and Codex directly extract by describing fields in natural language.
How to use Nutrient Data Extraction API
- 1First, run a batch of samples using `auto` to see which mode it routes to, then fix the mode based on accuracy, and don't use `agentic` for everything.
- 2The official website states that the free plan offers 5,000 credits per month with no credit card required; before going live, use the live test page to compare the outputs of each mode.
- 3Do not use the text mode for scanned documents and images, as the official website states that it only reads native digital PDFs.
- 4Add a rule or manual gate based on confidence scores and page number context. The official documentation clearly states that grounding allows errors to be reviewed, but it does not make them correct.
- 5For sensitive documents, first check the official website's compliance statement: the site is marked with annual SOC 2 Type 2 audits and offers optional processing regions.
Traffic & popularity
Data month Sep 2026
Nutrient Data Extraction API receives about 91.1K visits per month and ranks #519,972 worldwide.
Monthly visits
12 monthsTraffic sources
- Search64.9%
- Direct23.2%
- Social6.6%
- Referrals3.3%
- Mail1.0%
- Other0.9%
Top countries
- United States22.4%
- Sweden7.0%
- India5.2%
- Egypt5.1%
- Brazil3.9%
Estimated from third-party traffic data.
In these collections
Similar tools
 PerfectParserPerfectParser is a document extraction software positioned on its official website: describe the fields to be extracted in natural language, batch process files, scanned documents and images, and output table or interface data, which is suitable for replacing manual data entry.
 TextInThe intelligent document processing platform under Hehe Information can parse PDF, Office documents and scanned files into structured data, providing capabilities such as table formula recognition, document review and circulation, as well as image enhancement and watermark removal, targeting enterprise document automation.
 PDF.aiA platform that supports PDF dialogue and provides PDF APIs, which can answer questions, generate summaries and find answers. It can also parse documents, extract data and split files in its own workflow. The official website provides online tools and interface documents.
 Extend AIA document processing infrastructure for AI agents that parses, extracts and segments complex documents using dedicated vision models. The official claims it processes millions of pages daily and leads on benchmarks, making it easy for engineering teams to integrate.
 ChunkrA parsing interface for retrieval augmentation and document pipelines, which the official says can convert PDFs, images and tables into structured data usable by models, and provides layout analysis, OCR and structured extraction.
 MinerUIntelligent document analysis platform for Agents and RAG, supporting PDF, Word, PPT, Excel and image analysis, and capable of outputting structured results such as Markdown, JSON, and LaTeX.