

PerfectParser
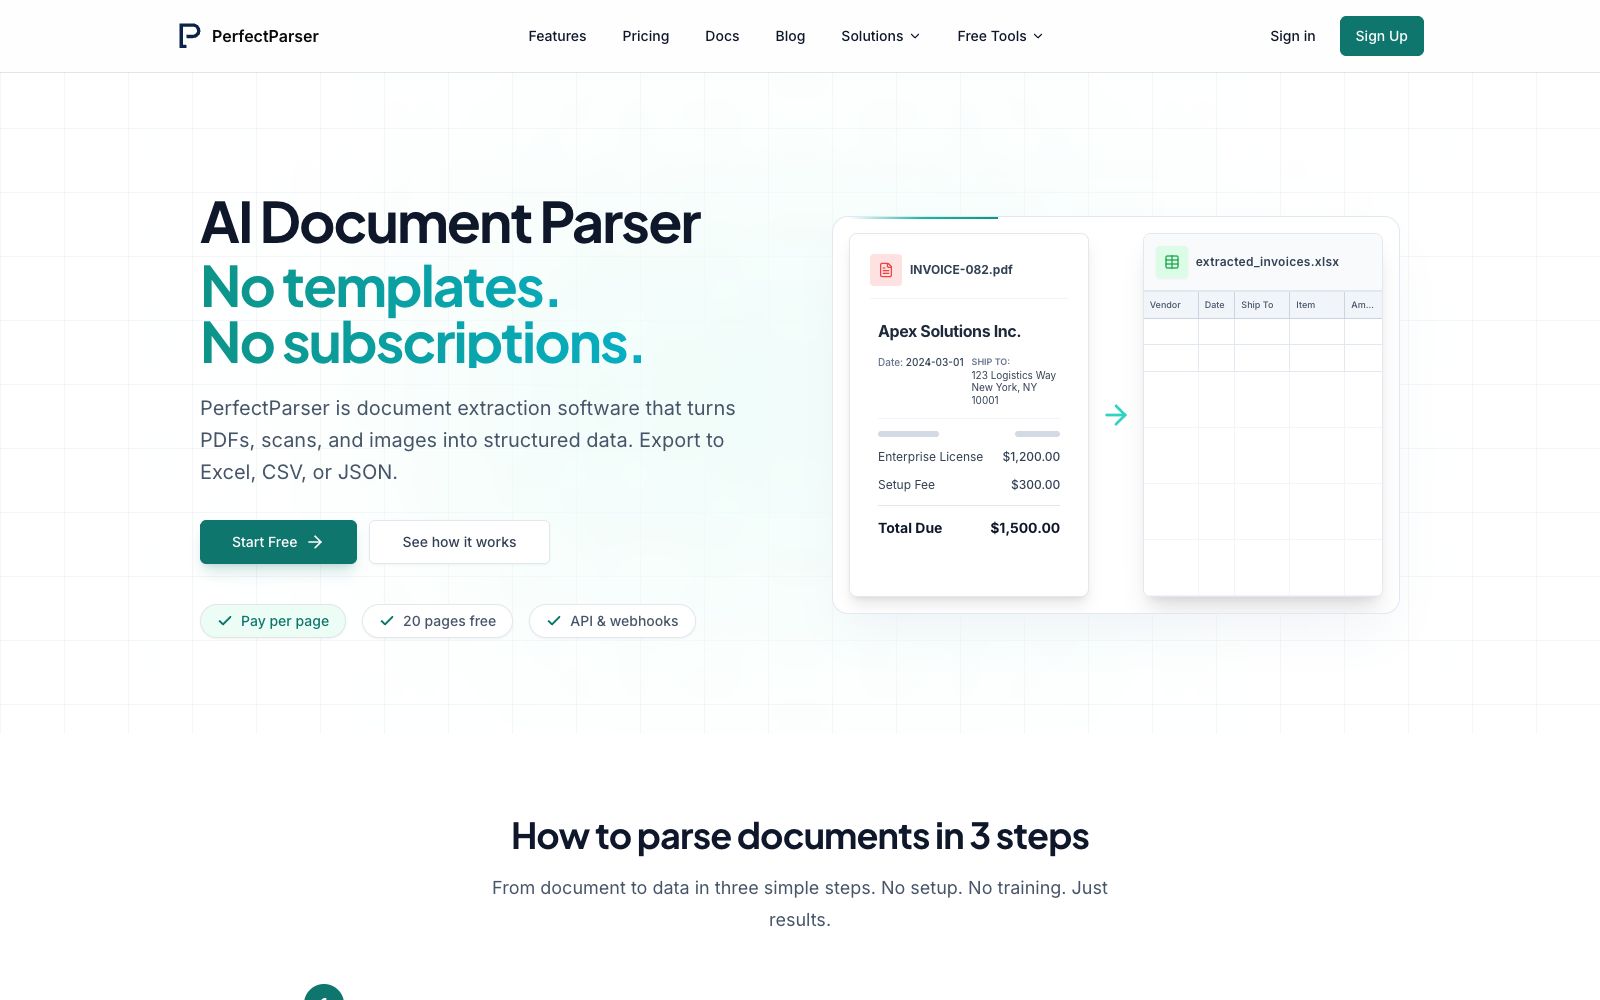
PerfectParser is a document extraction software positioned on its official website: describe the fields to be extracted in natural language, batch process files, scanned documents and images, and output table or interface data, which is suitable for replacing manual data entry.
Updated: 2026-10-27
What is PerfectParser?
The official website of PerfectParser positions it as a document extraction software for operations, finance and logistics teams. Its core scenario is converting documents such as invoices, contracts, packing lists and shipping labels into structured data. Compared with traditional template-based solutions, the official website emphasizes that users only need to state in natural language what fields they want to extract, without the need to configure templates or train models. The process is divided into three steps: creating a parser, batch extraction, and review and export, enabling non-technical roles to participate in automation.
Who is it for?
- Financial and logistics teams that process a large number of supplier invoices, packing lists or waybills every day.
- Operations personnel who do not have engineering resources but wish to configure parsing processes using sample files.
- Integration managers who need to connect extraction results to existing systems or automated processes.
- Small and medium-sized enterprises that frequently process contracts, bills and supply chain documents with different formats.
Key features
6Define fields with natural language
The official website states that after users upload sample files, they can directly tell the system which fields to extract, such as suppliers, amounts, dates or line items, and then create a parser.
Coverage of multiple document types
The official website lists the applicable types including invoices, bank statements, contracts, packing lists, shipping labels and bills of lading, and you can view more industry-specific solutions.
Batch Parallel Processing
The official website states that users can upload a large number of messy files at once, which are processed in parallel by the engine, and the system provides queue status and real-time extraction progress.
Complex Table Extraction
The official website states that it can automatically extract line items, variable layouts, and nested tables, preventing traditional parsers from failing when layouts change.
Structured Export & Integration
The official website states that results can be exported as tables or raw data objects, and also sent to downstream systems via APIs and callbacks.
Pay-as-you-go pricing by page
The official website states that one credit is consumed per page, and new users get 20 free credits upon registration; the credits are valid for 12 months, with no subscription or automatic renewal.
How to use PerfectParser
- First, use the 20 free pages of credit to run a batch of real historical files, check the field completeness rate and error patterns, and then purchase credit.
- Try to cover different vendor layouts, scanning qualities and table structures in the sample files, and avoid validating only with the neatest samples.
- When connecting to a downstream system for the first time, manually review all results first, and gradually reduce the sampling inspection ratio after the system stabilizes.
- Clarify sensitive fields and retention periods.
- The official website states that it provides privacy measures such as encryption, zero-model training, and automatic deletion, but you still need to confirm in conjunction with internal compliance requirements.
- The official website boasts an accuracy rate of over 90% and second-level processing speed.
- before launch, establish an independent test set using your own documents.
Traffic & popularity
Data month Sep 2026
PerfectParser receives about 8.1K visits per month and ranks #2,709,423 worldwide.
Monthly visits
8 monthsTraffic sources
- Direct30.1%
- Search29.3%
- Referrals12.8%
- Display ads8.2%
- Social7.1%
- Other12.5%
Top countries
- United States100.0%
Estimated from third-party traffic data.
Similar tools
 Nutrient Data Extraction APINutrient's cloud document extraction interface parses PDF, scanned documents, images and Office files into spatial JSON or Markdown with coordinates, confidence and page number context. It can also extract by field name with reference sources. The official website states that the free quota is 5,000 credits per month.
 AI DriveAI Drive is an intelligent document platform tailored for legal and professional scenarios. According to the official statement, it supports uploading PDFs, Word documents and scanned items, enables cross-folder conversations, and batch extracts structured data. It also provides OCR, custom intelligent agents and multi-model capabilities.
 FormX.aiDocument data extraction platform. The official website supports multiple types of documents such as invoices, receipts, bank statements, contracts and certificates. Build an extractor and connect the API in three steps, and the accuracy can be continuously optimized with production data.
 Extend AIA document processing infrastructure for AI agents that parses, extracts and segments complex documents using dedicated vision models. The official claims it processes millions of pages daily and leads on benchmarks, making it easy for engineering teams to integrate.
 PDF.aiA platform that supports PDF dialogue and provides PDF APIs, which can answer questions, generate summaries and find answers. It can also parse documents, extract data and split files in its own workflow. The official website provides online tools and interface documents.
 TextInThe intelligent document processing platform under Hehe Information can parse PDF, Office documents and scanned files into structured data, providing capabilities such as table formula recognition, document review and circulation, as well as image enhancement and watermark removal, targeting enterprise document automation.