

LlamaIndex
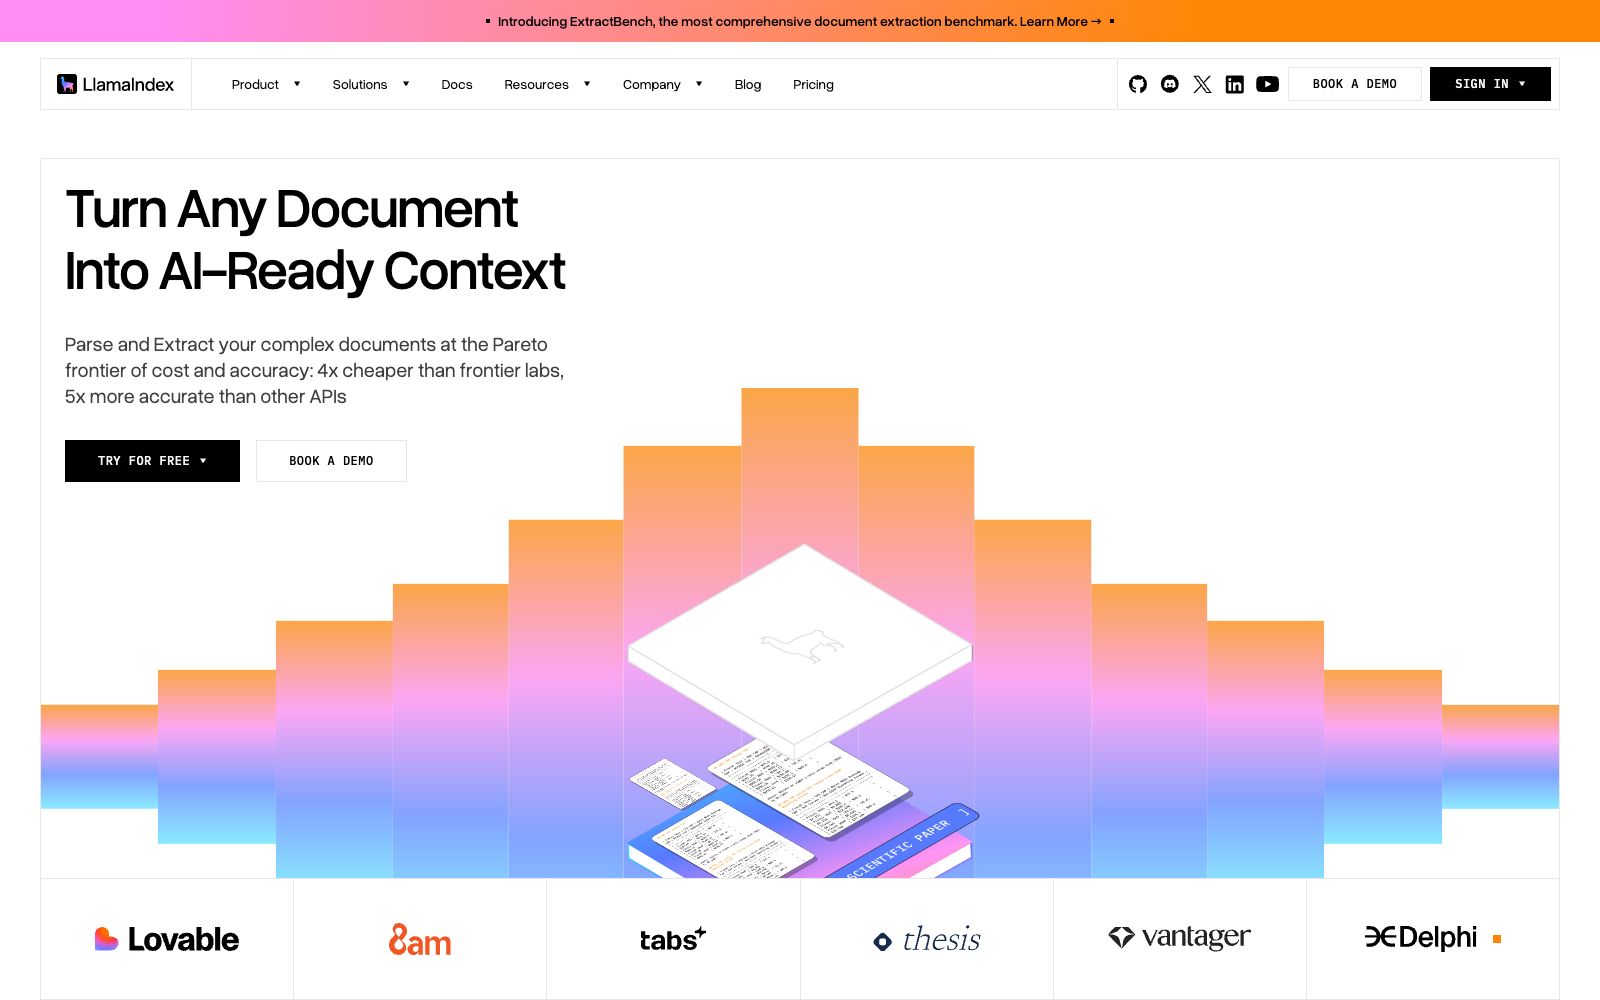
An AI data framework centered on document intelligence, its flagship capability LlamaParse uses agent-style OCR to parse documents with complex tables and charts into structured context usable by AI.
Updated: 2026-10-26
What is LlamaIndex?
LlamaIndex is an AI data framework centered on document intelligence. Its flagship capability promoted on the official website is LlamaParse, which the official calls "the world's best agent OCR". Specifically designed to handle documents with complex tables, charts and images, it aims to achieve parsing accuracy close to that of humans. The official positioning is to "turn any document into AI-ready context", and on this basis, it provides complete capabilities from parsing to indexing and then to document agents. The framework itself is fully open source, and the official claims that it is used by many leading AI teams in document-intensive industry scenarios. It also offers a complete toolchain from parsing to indexing, helping teams solidify their document processing capabilities into internal infrastructure.
Who is it for?
- Teams that need to feed a large volume of contracts, financial reports, research reports, and papers to AI, especially those in document-intensive industries such as finance, law, insurance, and healthcare; engineering teams that are developing RAG or document intelligent agents and require a high-quality parsing layer; as well as organizations with requirements for the boundaries of parsed data can leverage its local processing capabilities; it is also suitable for teams that need to digitize historical materials in batches.
Key features
6Agent OCR
Performs layout-aware analysis for documents with complex layouts. The official claims its accuracy is close to human level, covering challenging issues such as cluttered tables, charts, and images. The official emphasizes "Agentic Understanding" rather than simple rule-based parsing.
Structured Extraction
Extract fields according to the specified schema, and the parsed results can be directly fed into downstream processes without manual sorting.
All-in-One Document Processing
Covers stages such as Parse, Extract, Split, Classify, and Index, completing the entire process from parsing to segmentation, classification, and indexing in one go, and enabling the construction of end-to-end document agents.
Local Fast Processing
Offers fully open-source local processing capabilities that balance privacy and speed, making it suitable for scenarios with strict data boundary requirements.
Wide format coverage
Supports all mainstream document formats and can output bounding box positioning information to facilitate layout restoration and visualization.
Cost and Accuracy Advantage
The official claims that in terms of the balance between cost and accuracy, it is 4 times cheaper than cutting-edge lab solutions and 5 times more accurate than other APIs.
How to use LlamaIndex
- The free tier provides 10,000 credits per month (approximately 1,000 pages), which you can use first to verify the parsing effect of your own documents.
- Tables and multi-column layouts are the most error-prone parts.
- When choosing a solution, be sure to test with your messiest batch of documents and compare the parsed output with manual annotations.
- When comparing different parsing solutions, it is recommended to run a unified evaluation using the same batch of sample documents to avoid inconsistent metrics, and then decide whether to scale up the usage.
Things to know
Traffic & popularity
Data month Sep 2026
LlamaIndex receives about 102.0K visits per month and ranks #454,895 worldwide.
Monthly visits
12 monthsTraffic sources
- Search49.9%
- Direct30.9%
- Referrals7.7%
- Social5.0%
- AI assistants3.4%
- Other3.2%
Top countries
- United States26.1%
- India6.0%
- China4.9%
- Spain4.9%
- Canada3.8%
Estimated from third-party traffic data.
In these collections
Similar tools
 MinerUIntelligent document analysis platform for Agents and RAG, supporting PDF, Word, PPT, Excel and image analysis, and capable of outputting structured results such as Markdown, JSON, and LaTeX.
 TextInThe intelligent document processing platform under Hehe Information can parse PDF, Office documents and scanned files into structured data, providing capabilities such as table formula recognition, document review and circulation, as well as image enhancement and watermark removal, targeting enterprise document automation.
 Extend AIA document processing infrastructure for AI agents that parses, extracts and segments complex documents using dedicated vision models. The official claims it processes millions of pages daily and leads on benchmarks, making it easy for engineering teams to integrate.
 ChunkrA parsing interface for retrieval augmentation and document pipelines, which the official says can convert PDFs, images and tables into structured data usable by models, and provides layout analysis, OCR and structured extraction.
 Upstage AIAn AI platform for enterprise document workflows offers document parsing, structured information extraction, and in-house large language models. According to the official statement, it serves industries such as insurance, finance, healthcare, and manufacturing, and supports cloud, on-premises, and marketplace deployments.
 Sharp APISharp API provides more than 30 pre-built AI API endpoints, covering resume parsing, invoice parsing, 80+ language translation and e-commerce copywriting, outputting clean JSON and providing full-language SDKs.