

LLM Stats
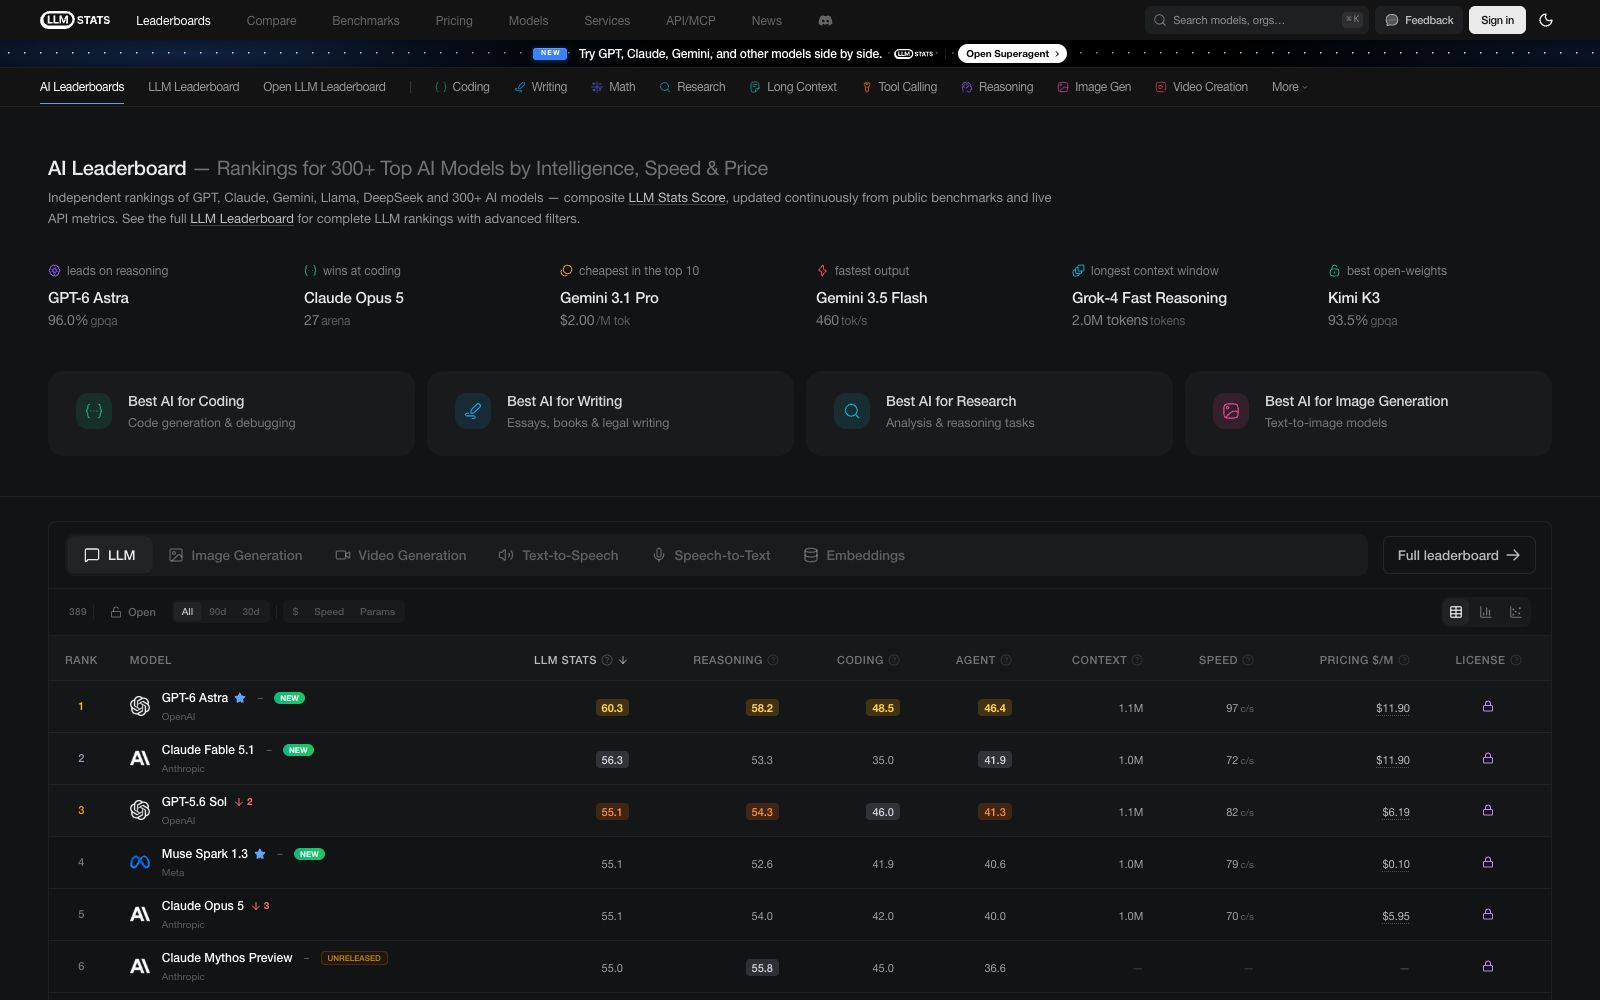
An independent ranking that converts the intelligence level, speed and price of over 300 AI models into a single comprehensive score. The data is continuously updated from public benchmarks and real API metrics, supporting multi-task dimension ranking.
Updated: 2026-10-26
What is LLM Stats?
When the model evaluation lists on the market each have their own criteria, LLM Stats' approach is to distill "which model to choose" into a comparable single score. It covers more than 300 models such as GPT, Claude, Gemini, Llama, and DeepSeek, using its self-built LLM Stats Score to comprehensively evaluate three dimensions: intelligence, speed, and price. Its data comes from public benchmarks plus real-time API metrics, rather than self-reported data from manufacturers. Officially positioned as an independent and continuously updated AI ranking, the page directly promises to "rank the best AI models with an independent score".
Who is it for?
- Engineering and product teams that select models, practitioners who need to quickly determine "which is the strongest right now," authors who reference ranking data in industry analyses, and developers who want to track the progress of open-source models and evaluate self-deployment solutions.
Key features
5Single Comprehensive Score
Converts multiple dimensions such as intelligence, speed, and price into a single LLM Stats Score, eliminating the hassle of comparing items one by one, and enabling quick judgment of the overall performance level and relative position of the model.
Multi-dimensional leaderboards
In addition to the overall leaderboard, there are separate rankings for tasks such as coding, writing, mathematics, research, long context, tool calling, reasoning, image generation, and video generation, covering mainstream application directions to facilitate filtering by scenario.
Open-Source Model Leaderboard
Lists the rankings of open-weight models separately, making it easy to evaluate options that can be self-deployed with controllable costs and meeting the needs of teams that require data sovereignty.
Continuous Updates
When new models are launched, they are added to the rankings, and real-time changes in API-side speed and pricing are incorporated; the page provides a list of new models and their performance indices, making it easy to track the latest releases.
Supporting Resources
It also provides an arena and a benchmark data portal, enabling cross-verification beyond the single score to understand performance across different evaluation systems. It also allows actual battle testing of models, aligning subjective experiences with objective scores.
How to use LLM Stats
- First, use the overall score to lock a candidate range, then conduct a second round of screening based on the sub-score you care about most (such as coding, long context, or reasoning).
- Before actual integration, it's best to run a small-scale comparison with your real set of prompts, because the overall score represents the average level and does not reflect the performance in your specific scenario.
- If you care about costs, you can regularly check price-related indicators—after a model's price reduction, its cost-performance ratio ranking often changes significantly, and the overall score list can help you seize such opportunities in a timely manner.
- during the period when new models are released intensively, it's recommended to check the ranking once a week to keep track of changes in a timely manner.
Things to know
Traffic & popularity
Data month Sep 2026
LLM Stats receives about 546.0K visits per month and ranks #104,333 worldwide.
Monthly visits
12 monthsTraffic sources
- Search54.8%
- Direct36.3%
- Referrals5.2%
- Social1.9%
- AI assistants1.0%
- Other0.8%
Top countries
- United States22.6%
- China8.6%
- Germany5.7%
- India5.1%
- France3.9%
Estimated from third-party traffic data.
Similar tools
 Artificial AnalysisA benchmark platform for independently evaluating AI models and API service providers, conducting horizontal comparisons based on intelligence indices, output speeds and single-task costs, and covering multi-category rankings such as coding, speech, image and video, as well as comparisons with search service providers.
 ArenaA crowdsourced AI model arena where two models compete anonymously and users vote to determine the winner. Based on the results, public leaderboards for LLM, image, and code models are generated. It comes with built-in task templates such as landing pages, dashboards, and mini-games that can be directly tested in practice.
 SEAL LLM LeaderboardThe expert-driven evaluation list produced by the labs under Scale AI covers more than 20 benchmarks and over 100 models including agent programming, cutting-edge reasoning and safety alignment. It can be browsed by capability tiers and is continuously updated.
 ChatHubA comparison tool that places multiple chatbots side by side, sends the same question to multiple models simultaneously, supports image generation, file analysis and web search, and is available on web, mobile and desktop platforms.
 MachineTranslationThe free AI translator launched by Tomedes aggregates the results of 22 AI models, provides AI verification, retention of document layout and on-demand human proofreading, and the official claims that it has over one million users.