

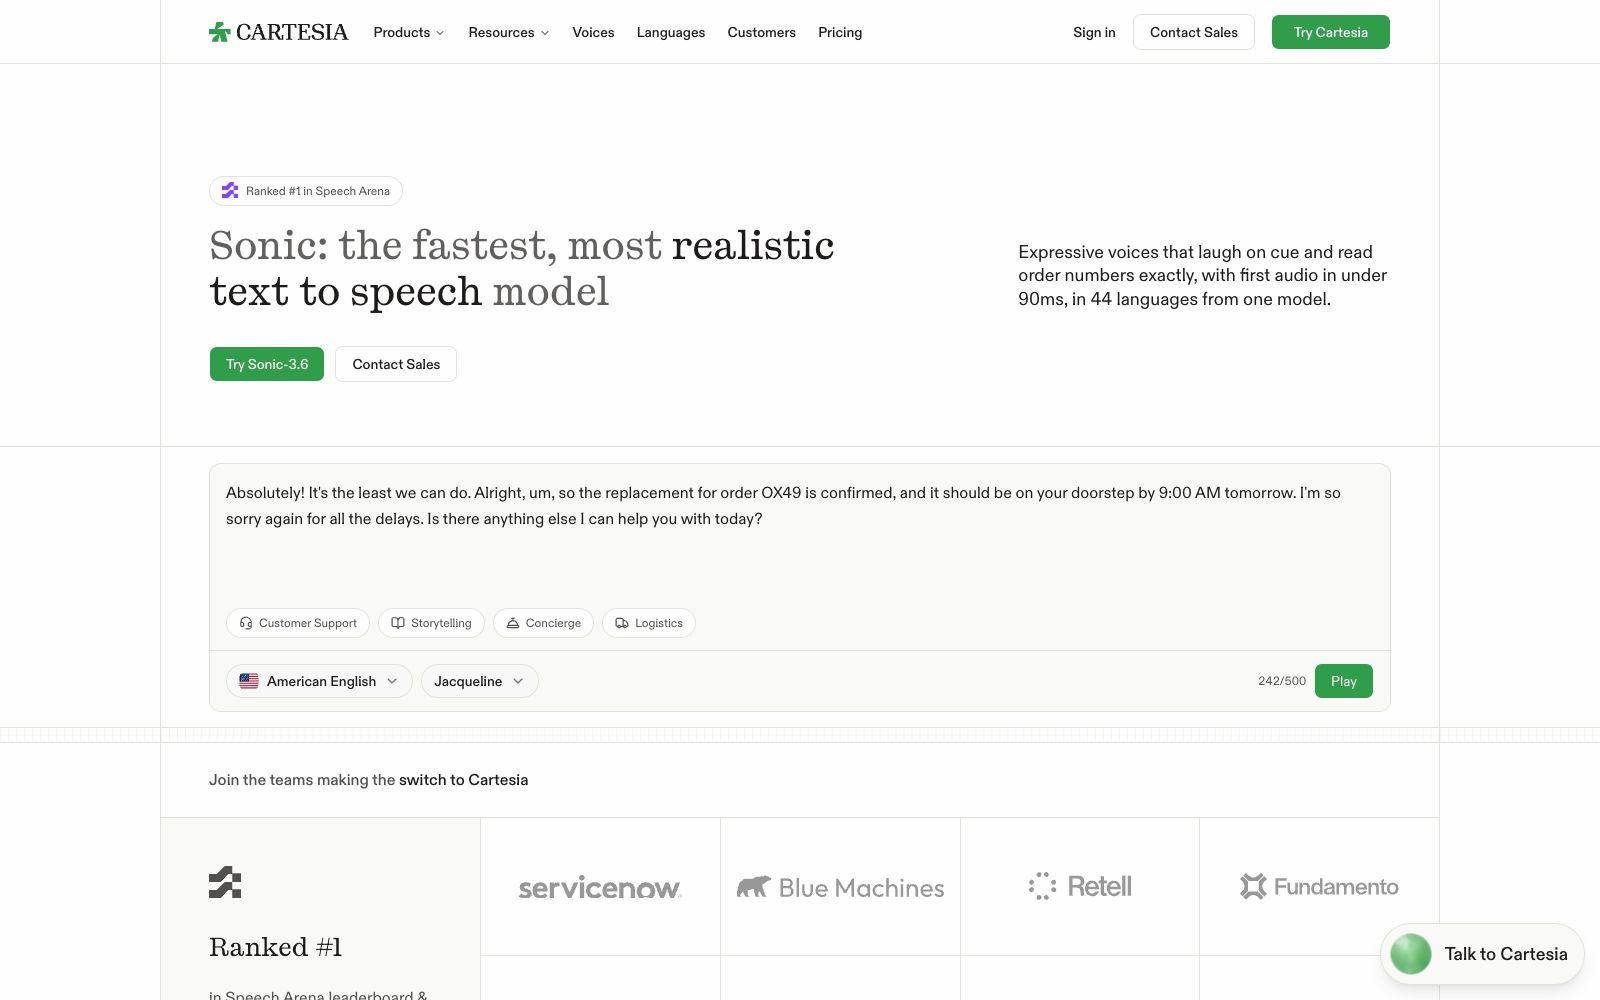
Sonic-3
Cartesia's real-time speech synthesis model, officially claimed as the first with an audio package below 90 milliseconds, a single model covering 44 languages, supporting voice cloning and custom pronunciation dictionaries, is mainly targeted at the voice Agent scenario.
Updated: 2026-10-27
What is Sonic-3?
Sonic-3 is Cartesia's real-time text-to-speech (TTS) model, and its official page currently promotes Sonic-3.6. It is not targeted at dubbing export but at voice agents: it requires almost no waiting during conversations while pronouncing tones, numbers, and proper nouns correctly. For teams building voice products, the priority order for choosing a TTS is usually latency, followed by stability, and finally, how pleasant the voice sounds. The official page also offers two other product lines: speech recognition and hosted agents, making it easy to integrate recognition, synthesis, and conversation.
Who is it for?
- Teams building voice customer service and call centers: Require low latency and stable call handling.
- Voice Agent developers: Integrate real-time TTS as a layer in the dialogue chain into their products.
- Overseas product teams: One system needs to cover multilingual broadcasting.
- Teams for audio content and brand broadcasting: Need a unified timbre and accurate pronunciation.
- Logistics and order-related businesses: Need to accurately read out order numbers, amounts, and addresses.
Key features
6Low Latency
The official states that the first audio packet is returned within 90 milliseconds, which is a key metric for real-time conversation capability; end-to-end latency also includes speech recognition and network time.
Single model supporting 44 languages
The official states that one model covers 44 languages, facilitating the launch of the same system for multilingual use. There is no need to maintain separate models for each language, and the same voice can be reused across languages.
Expressiveness
The official description states that the voice can laugh at the right moments and accurately read out numeric strings such as order numbers, making it suitable for customer service and announcement scenarios; the tone and rhythm are adjusted according to the context, and the official goal is to make conversations sound like a human speaking.
Voice Cloning
The official lists voice cloning as an independent capability, allowing the replication of timbres for unified brand announcements.
Custom Pronunciation Dictionary
You can set the pronunciation for your own personal names, brand names and abbreviations to avoid misreading them every time, and also to maintain consistency in mixed Chinese-English text; the dictionary is maintained on a project basis, and you can set different pronunciations for the same brand name for different languages.
Deployment and Security
The official states that enterprise-grade deployment options from cloud to on-premises are available, and additionally, the Ink speech recognition and hosted Agent products can be integrated.
How to use Sonic-3
- First, use the real text from your business for a trial listen, focusing on numbers, amounts, abbreviations, and mixed Chinese and English, then compare the stability of the same sentence with three different tones.
- Add the words that are often mispronounced to the pronunciation dictionary at one time, which is more effective than repeatedly modifying the text.
- Before cloning a voice, you must obtain written authorization from the voice rights holder, and you are also required to comply with the official usage policies.
- Before launching in multiple languages, have native speakers listen to each language separately.
- don't just rely on the official language list.
- Latency is an official specification.
- the actual value depends on the network and deployment method.
- Conduct end-to-end stress testing before launch.
- Refer to the official website for pricing and commercial authorization.
Traffic & popularity
Data month Sep 2026
Sonic-3 receives about 348.1K visits per month and ranks #97,458 worldwide.
Monthly visits
12 monthsTraffic sources
- Direct47.1%
- Search35.6%
- Referrals5.7%
- Social5.7%
- Display ads3.4%
- Other2.5%
Top countries
- United States24.6%
- India21.2%
- Bangladesh18.1%
- Brazil3.5%
- Israel2.1%
Estimated from third-party traffic data.
Similar tools
 DubverseDubverse is a multilingual voice platform that offers video dubbing, automatic subtitles, and text-to-speech functions. It has more than 200 built-in voices and supports brand voice cloning, enabling batch processing of multilingual mixed scripts, making it ideal for teams that need to distribute content to multilingual markets.
 UnmuteThe voice interaction project Unmute launched by Kyutai is officially described as "enabling large language models to listen and speak", with the goal of endowing LLMs with real-time auditory and speech capabilities; its official website is a dynamically loaded page with limited publicly visible details.
 Bland AIEnterprise-level voice intelligent agent platform: build AI agents that can make and receive calls using self-developed models. During calls, they can check accounts, verify identities and modify bills. The official website states that it has compliance qualifications such as HIPAA.
 VoiceboxAn open-source local voice studio that clones timbre from a few recordings, generates speech across multiple TTS engines, and enables global dictation in any application. The official description states that it is a free local alternative to ElevenLabs and WisprFlow.
 SpeechGenSpeechGen.io is an online text-to-speech tool. According to the official statement, it offers over 5,000 voices and 150 languages, supports MP3/WAV/FLAC export and multi-character dialogue, charges by the number of characters, and is suitable for short video dubbing and courseware.
 ApplioApplio is an open-source and free AI voice conversion suite that can convert audio into any timbre, perform real-time voice changing, support training timbre models with your own data, and run locally without an account. It is suitable for creators who do covers, live broadcast voice changing and dubbing.