

Wusheng AI
A hyper-realistic AI voice synthesis and instant cloning platform (formerly Reecho), the official claims that the self-developed text-to-speech model supports over 30 languages and dialects, can clone voices with a minimum 3-second sample, and offers a voice marketplace and low-latency APIs.
Updated: 2026-10-26
What is Wusheng AI?
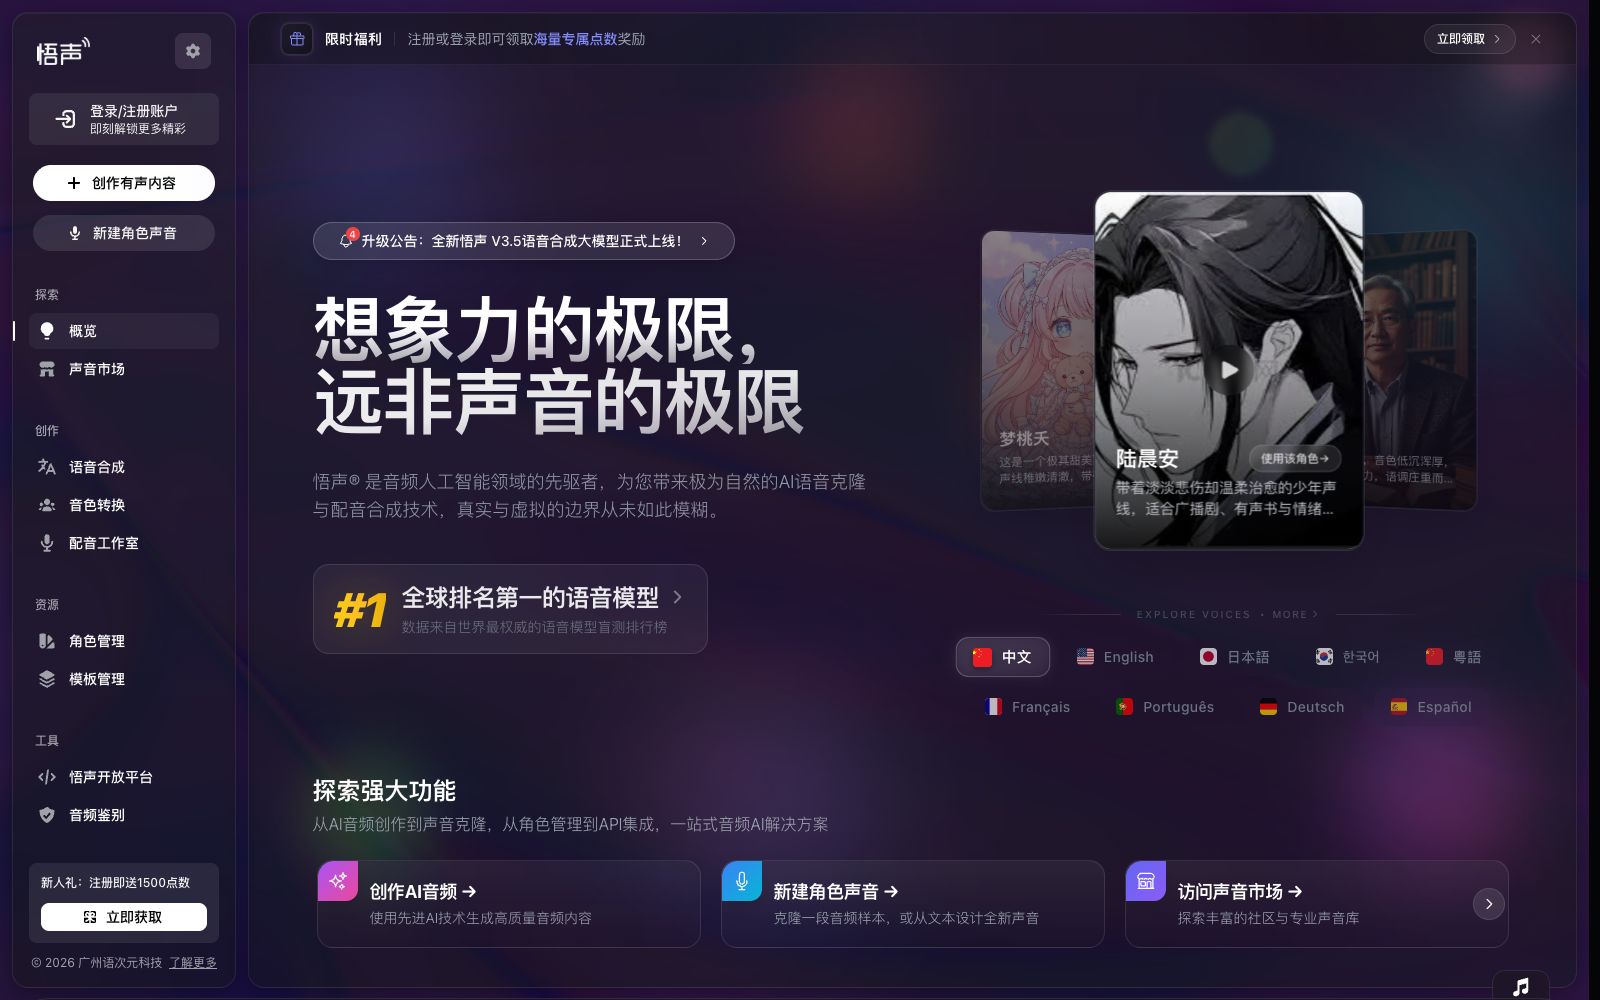
Wusheng AI (formerly Reecho) is an ultra-realistic AI voice synthesis and real-time cloning platform. The official website claims to be "the world's number one ultra-realistic AI voice synthesis and real-time cloning platform", marks itself as the "#1 ranked voice model globally", and states that the data comes from the world's most authoritative voice model blind test rankings. Operated by Guangzhou Yuciyuan Technology, the official website announcement shows that the brand-new Wusheng V3.5 voice synthesis large model has been officially launched. Unlike dubbing tools that only provide a fixed list of timbres, Wusheng takes "characters" as its core organizational approach: the platform displays a large number of timbres with character profile descriptions, and supports cloning voices from extremely short samples.
Who is it for?
- Creators who produce radio dramas, audiobooks, and character dubbing, who need emotional character voice lines
- Teams developing games and virtual characters who use character voices to maintain consistency in character personas
- Teams with cross-lingual content needs create multi-language versions through mixed multilingual creation
- Developers building real-time products such as voice assistants and automated customer service, who opt for low-latency APIs
- Individual users who want to quickly turn a piece of existing audio into their own exclusive voice tone
Key features
6V3 Series Text-to-Speech Large Model
The official website states that the V3 Series is a SOTA-level text-to-speech large model, supporting more than 30 local languages and accents. It can independently understand the context of text without intervention and generate audio with expressiveness, emotions, rhythm and tone close to those of real humans.
Instant Voice Cloning
The official claims to support instant voice cloning with the shortest 3-second sample, and also allows for high-precision professional voice cloning using longer samples.
Multilingual Mixed Creation
The official website states that the current version provides seamless support for over 30 languages and dialects, and multiple languages can be freely mixed in both cloning and synthesis.
Vocal Effect Performance
The official claims that it has learned various human voices through training on millions of hours of content, and can vividly perform human vocal effects such as laughter, crying, and humming through samples and text prompts.
Speech Synthesis and Voice Timbre Conversion
The creation section offers a speech synthesis tool, a voice timbre conversion tool, and a dubbing studio, along with character management and template management functions to organize materials.
Developer API
The Wusheng Open Platform provides APIs. The official states that with sufficient resources, it can achieve hundreds-of-millisecond-level streaming responses to meet the real-time needs of voice assistants, automated customer service, etc. It also offers customized services such as exclusive inference resource deployment, expert support, and high availability guarantee.
How to use Wusheng AI
- First go to the Voice Market for a trial listen before deciding which voice to use: Each voice on the platform comes with a character profile description, and its applicable scenarios cover news broadcasting, healing-style radio dramas, role-playing, etc.
- Choosing by usage is more accurate than choosing by name.
- For the cloning function, it is recommended to first use an extremely short 3-second sample to quickly verify the similarity.
- After confirming the direction, supplement with a longer sample for professional cloning, and the effect will be more stable.
- You can appropriately add emotion hints in the copy.
- The official states that the model will independently understand the context, and vocal effects such as laughing, crying, and humming can be triggered through samples and text prompts.
- For development access, use the Wusheng Open Platform.
- For real-time scenarios, pay attention to streaming response latency, and the official website states that it can reach the hundreds-of-millisecond level.
- for businesses with high stability requirements, you can negotiate exclusive inference resource deployment.
- The official website shows that 1500 points are given for free upon registration, and the specific quota and billing shall be subject to the instructions on the current page.
- Cloning and commercial release of others' voices must first obtain authorization, and the platform also provides an audio identification tool to assist in judgment.
Traffic & popularity
Data month Sep 2026
Wusheng AI receives about 865.4K visits per month and ranks #11,945,073 worldwide.
Monthly visits
12 monthsEstimated from third-party traffic data.
In these collections
Similar tools
 MiniMax VoiceMiniMax's Speech and Music Generation Platform, officially powered by Speech 2.6 and Music 2.0, offers speech synthesis, timbre design, voice cloning and music creation, and supports vocal extraction and API access.
 VoicvVoicv is a voice cloning and synthesis platform that provides zero-shot voice cloning, text-to-speech and speech-to-text services. It supports multiple languages, emotion control and real-time processing, and includes AI digital humans and API access.
 Doubao VoiceVolcano Engine's large-scale speech model product line covers capabilities such as speech synthesis, voice cloning, speech recognition, real-time speech and audio generation. The official statement mentions that it provides over 400 timbres and more than 30 languages, and supports API and SDK access for enterprises.
 Soniox Text-to-SpeechSoniox Text-to-Speech is a real-time speech synthesis interface. Its official website states that it supports more than 60 languages and over 200 timbres. Labels can be used to control emotions and tones, and timbres can be cloned with just a few seconds of samples. It is charged based on the generation duration.
 AnyVoiceOnline AI voice cloning tool. The official claims that it can replicate the tone with just 3 seconds of audio. It supports text-to-speech and sound design, with a built-in voice model library covering Chinese, English, Japanese and Korean languages.
 TypecastA highly expressive AI voice generator, the official website states it offers 700+ AI voices, allowing adjustment of emotion, speed and intensity. Some voices are authorized from real voice actors, targeting creators, developers and enterprises.