

SuperCLUE
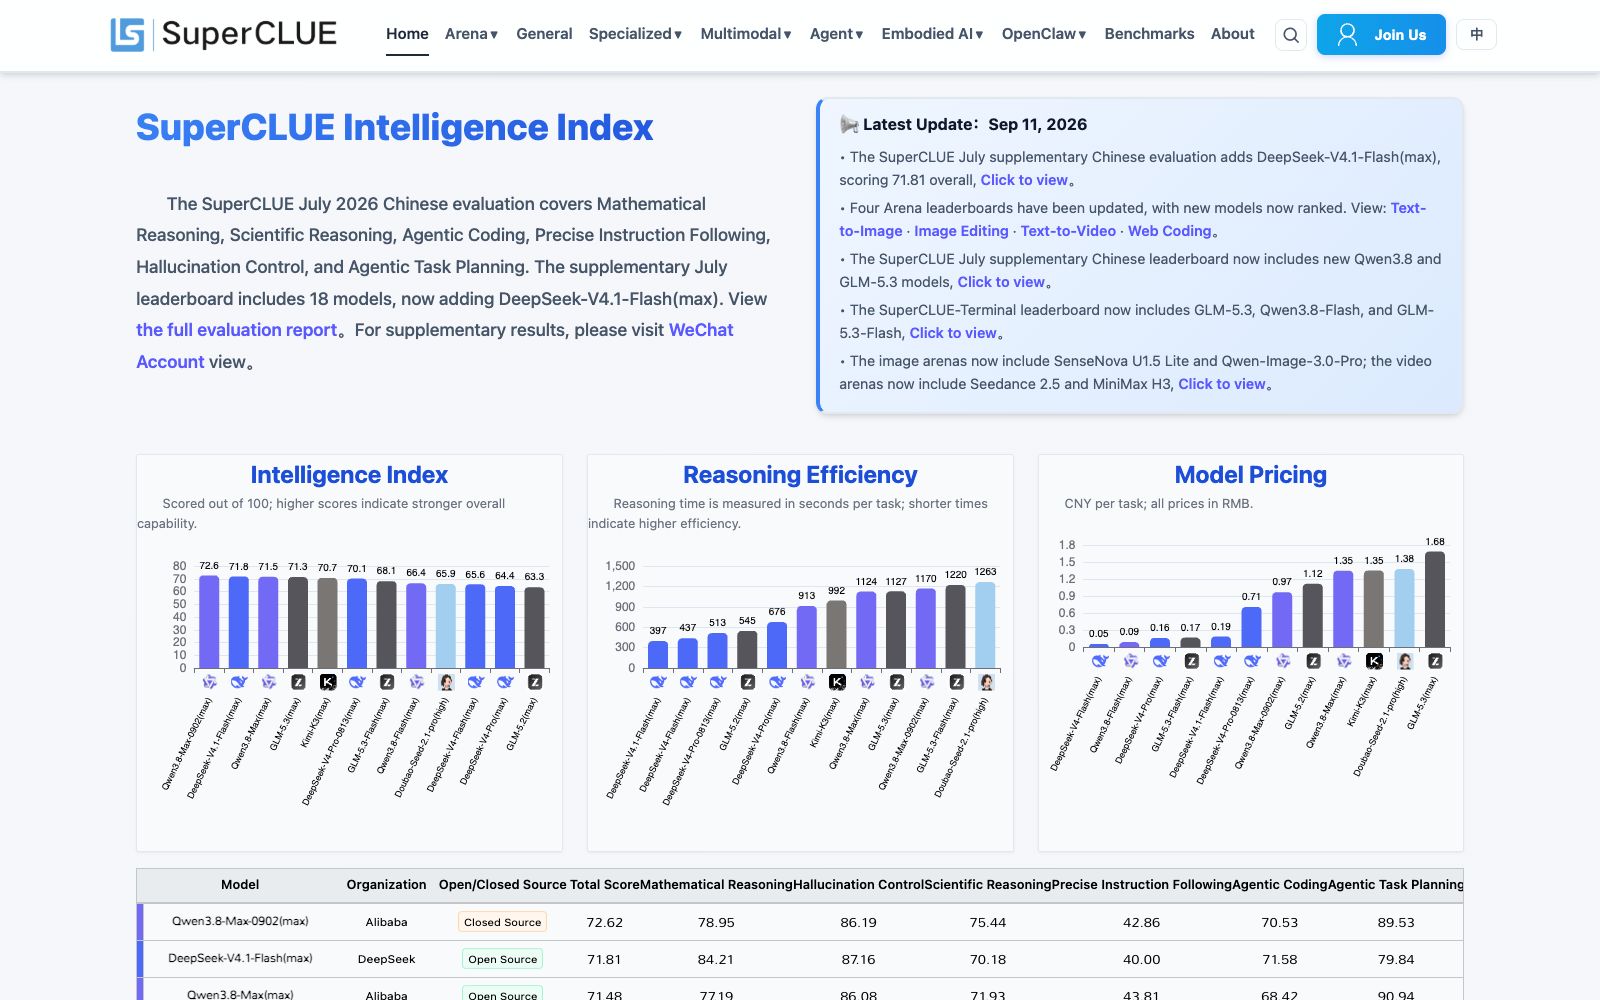
The Chinese large model evaluation benchmark, officially stated, presents model performance through a general capability overall ranking and sub-rankings such as mathematical reasoning, hallucination control, scientific reasoning, precise instruction following, and agent programming, and simultaneously provides model pricing and task planning consumption data.
Updated: 2026-10-30
What is SuperCLUE?
SuperCLUE is an evaluation benchmark for Chinese large models. The official version provides a general capability leaderboard and sub-item leaderboards such as mathematical reasoning, hallucination control, scientific reasoning, precise instruction following, agent programming, and agent task planning. It also provides token consumption data for model pricing and Agentic task planning. To reduce score fluctuations, the official regulation states that models with a difference of less than one point are treated as tied. International models and some domestic models do not participate in the ranking and are only for reference.
Who is it for?
- Enterprise selection decision-makers: Evaluate model capability scores alongside pricing to avoid making decisions based solely on single leaderboard rankings.
- Algorithm engineers: Use the sub-item rankings to identify the model's shortcomings in hallucination control or instruction following, and decide whether fine-tuning is needed.
- Product managers: Select models that perform better in the corresponding dimensions according to business scenarios, such as those with strong reasoning capabilities or strong instruction following capabilities.
- Researchers or media practitioners: Cite traceable evaluation metrics and evaluation dates to avoid using rankings without sources.
- Teams concerned about inference costs: Refer to the Token consumption data to estimate the call costs for Agentic applications.
Key features
6General Ability Overall Ranking
The official ranks models by their total scores and displays fields such as open-source or closed-source, access method, whether it is a reasoning model, and evaluation date.
Sub-capability Rankings
The official provides scores for dimensions such as mathematical reasoning, hallucination control, scientific reasoning, precise instruction following, agent programming, and agent task planning.
Model Pricing Information
The official provides a Model Pricing section, making it easy to compare capability scores with invocation costs.
Token Consumption Data
The official presents the difference in consumption of models when completing similar tasks based on the average number of Tokens per task in Agentic task planning.
Region & Access Method Filtering
The official platform supports filtering by open-source or closed-source status and access methods, helping users view results based on accessibility.
Leaderboard Chart Download
The official states that the results of the leaderboards are available for image download, making it convenient to cite them in reports and materials.
How to use SuperCLUE
- First, confirm the evaluation date and model version.
- The rankings on the leaderboard change frequently with model updates, and drawing conclusions from outdated data is likely to be misleading.
- Treat the leaderboard as a screening tool rather than a conclusion.
- Before making a selection, be sure to conduct small-scale actual tests using your own business data.
- Pay attention to the tie-handling rule.
- models with very small score differences should not be regarded as having obvious gaps in capabilities.
- For sub-scores, you should view them in light of business priorities: customer service scenarios care more about hallucination control, while coding scenarios prioritize programming and instruction following capabilities.
- When citing data, retain the evaluator's name and the time to avoid misinterpretation caused by the loss of methodological context in secondary dissemination.
- In addition, such tools that are more infrastructure- and community-oriented often reveal their value only after being used for a period of time: spend a bit more time familiarizing yourself with their data structures and interface conventions early on, and the cost of integrating them into your own workflow afterward will decrease significantly.
Traffic & popularity
Data month Sep 2026
SuperCLUE receives about 149.7K visits per month and ranks #226,134 worldwide.
Monthly visits
12 monthsTraffic sources
- Direct41.3%
- Search37.4%
- Referrals18.5%
- Social2.5%
- AI assistants0.4%
Top countries
- China78.9%
- United States5.5%
- Singapore5.4%
- Hong Kong, China5.3%
- Taiwan, China1.9%
Estimated from third-party traffic data.
Similar tools
 FlagEval LibraThe large model evaluation system and open platform of the Beijing Academy of Artificial Intelligence (BAAI) is officially claimed to cover four evaluation scenarios: language, multimodality, computer vision and speech, and provides rankings, a large model arena, as well as a collection of evaluation methods and tools that combine automatic and manual evaluation.
 AI Product RankingAI Product Ranking Data Platform. Officially, it ranks AI product lists by user size and AI model lists by price. It regularly releases global general rankings, domestic general rankings, overseas general rankings, as well as rankings for various track segments and growth speed rankings, which are widely cited by media and consulting institutions.
 Luchen TechnologyAn enterprise developing and deploying an AI large model platform, officially stating that its self-developed Colossal-AI covers the entire chain of training, fine-tuning, inference and deployment, and Luchen Cloud provides pay-as-you-go GPU computing power and Token factory-style MaaS services.
 AGI-EvalAGI-Eval is a large model evaluation community that provides evaluation leaderboards, evaluation datasets, human-machine competitions and Data Studio, helping selectors understand the strengths and weaknesses of various models with transparent and authoritative scores.
 SuperBenchThe Comprehensive Capability Evaluation Ranking of Large Models, released by the Tsinghua University Center for Basic Model Research in collaboration with the Zhongguancun Laboratory, promotes fair, open, and systematic large model evaluation and technological progress through bi-monthly reports.
 Fireworks AIA training and inference platform for open-source models, the official website states that it can transform open models into exclusive intelligence, supports calling the latest models with a single line of code, and provides multiple paths from guided training to reinforcement learning.