


TextIn
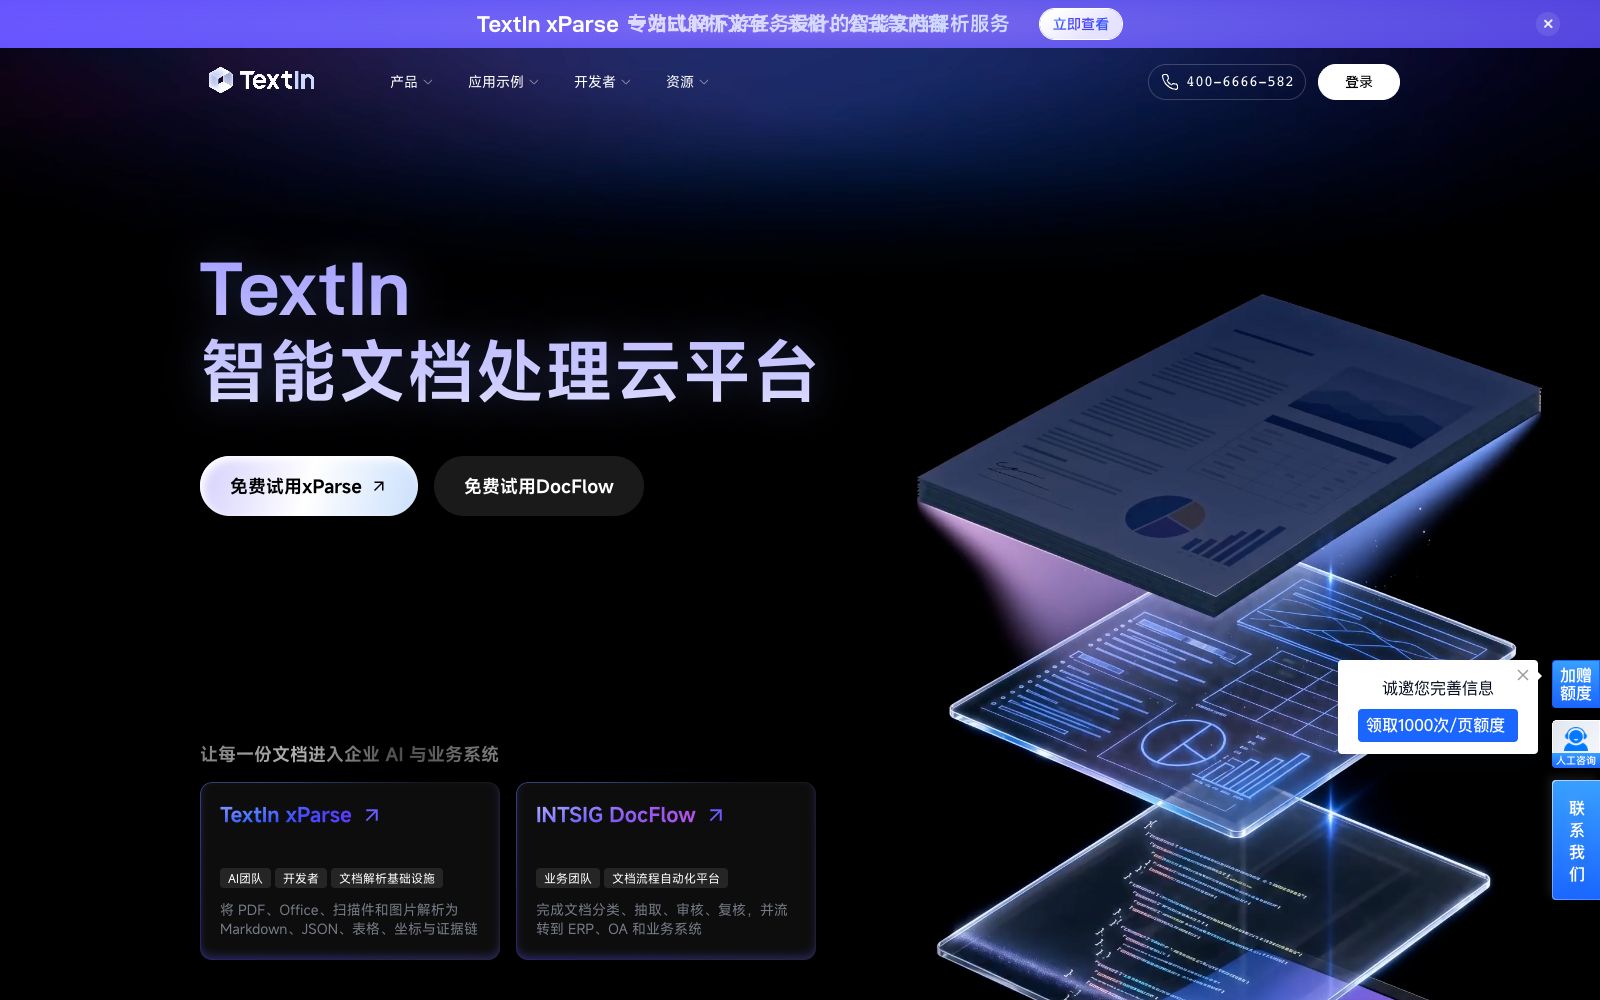
The intelligent document processing platform under Hehe Information can parse PDF, Office documents and scanned files into structured data, providing capabilities such as table formula recognition, document review and circulation, as well as image enhancement and watermark removal, targeting enterprise document automation.
Updated: 2026-10-26
What is TextIn?
TextIn is an intelligent document processing cloud platform launched by Hehe Information, and its official website positions itself as a document parsing infrastructure. It parses PDF, Office files, scanned copies and images into Markdown, JSON, tables, coordinates and evidence chains, and further supports document process automation at the upper layer. Compared with tools that only perform general optical character recognition, it places greater emphasis on long document structures, complex tables and traceable evidence chains, targeting large-scale enterprise document processing scenarios.
Who is it for?
- Enterprise AI middle platform and knowledge base teams: Need to convert a large volume of existing documents into structured data for retrieval and model invocation.
- Finance and supply chain departments: Perform classification and extraction of bills, invoices and waybills, and expect to automatically feed back the results to business systems.
- Legal and credit review positions: Require contract clause extraction, qualification review and risk identification, while maintaining a traceable review process.
- Large organizations with private deployment requirements: Need log auditing, permission control, and compatibility with domestic software and hardware.
Key features
6Document Parsing xParse
Officially, it can parse documents in various formats into text, tables, table of contents, coordinates and evidence chains, and supports the restoration of complex tables and long document structures.
Document Process Automation DocFlow
Enables business teams to complete document classification, extraction, review and recheck, and circulates to ERP, OA and business systems, covering document types such as invoices, contracts and waybills.
Multi-language Access Example
Provides cloud APIs, and official examples cover calling methods such as curl, Java, Python, Node.js, C#, and PHP, enabling developers to quickly integrate and verify.
Image Preprocessing Capability
Provides functions such as document image deskewing, perspective correction and enhancement, as well as automatic erasure of handwritten text and removal of watermark interference, to improve the quality of subsequent recognition.
Authenticity Detection
Provides universal tampering detection, authenticity verification, and AI image detection, serving scenarios such as quality scoring, clarity detection, and anti-fraud.
Enterprise-level Deployment
Supports private deployment models. The official claims that it has high concurrency, log auditing, permission control, and adaptation capabilities for domestic software and hardware, making it suitable for group-level AI middle platforms.
How to use TextIn
- 1First, conduct accuracy verification using a set of real layouts, especially cross-page tables and scanned documents, where the actual differences are often more significant than those in general promotional materials.
- 2It is recommended to retain the coordinate and chain of evidence fields in the analysis results to facilitate subsequent manual review and audit, instead of only keeping the final structured results.
- 3Before integration, confirm the call quotas, concurrency limits and failure retry strategies to avoid batch tasks failing collectively during peak hours and affecting business operations.
- 4When processing documents containing sensitive information, prioritize evaluating a private deployment solution and clarify the data retention period and destruction policy.
Traffic & popularity
Data month Sep 2026
TextIn receives about 21.3K visits per month and ranks #1,247,203 worldwide.
Monthly visits
12 monthsTraffic sources
- Direct48.4%
- Search43.3%
- Referrals6.9%
- Social0.8%
- Mail0.5%
Top countries
- China77.0%
- United States9.8%
- Taiwan, China2.6%
- Singapore2.1%
- Hong Kong, China1.9%
Estimated from third-party traffic data.
Similar tools
 LlamaIndexAn AI data framework centered on document intelligence, its flagship capability LlamaParse uses agent-style OCR to parse documents with complex tables and charts into structured context usable by AI.
 Nutrient Data Extraction APINutrient's cloud document extraction interface parses PDF, scanned documents, images and Office files into spatial JSON or Markdown with coordinates, confidence and page number context. It can also extract by field name with reference sources. The official website states that the free quota is 5,000 credits per month.
 Upstage AIAn AI platform for enterprise document workflows offers document parsing, structured information extraction, and in-house large language models. According to the official statement, it serves industries such as insurance, finance, healthcare, and manufacturing, and supports cloud, on-premises, and marketplace deployments.
 MinerUIntelligent document analysis platform for Agents and RAG, supporting PDF, Word, PPT, Excel and image analysis, and capable of outputting structured results such as Markdown, JSON, and LaTeX.
 PDF.aiA platform that supports PDF dialogue and provides PDF APIs, which can answer questions, generate summaries and find answers. It can also parse documents, extract data and split files in its own workflow. The official website provides online tools and interface documents.
 PerfectParserPerfectParser is a document extraction software positioned on its official website: describe the fields to be extracted in natural language, batch process files, scanned documents and images, and output table or interface data, which is suitable for replacing manual data entry.